


AI-Optimized Semiconductors: Why Better PPA Is Not Enough
Quick Overview
Problem: Machine learning improves power, performance and area. Those gains describe implementation quality, not conformance to requirements or correct behavior under real firmware.
Common failure points: Specification intent that never reaches the RTL; generated logic checked against a testbench derived from the same reading of the spec; verification plans whose coverage model omits the interactions integration will actually produce; power-state behavior validated without power intent; firmware that first meets real RTL after tape-out.
Where it appears: AI-assisted RTL-to-GDSII flows, custom SoC and accelerator programs, RISC-V silicon, IP-integration-heavy designs where third-party blocks arrive verified in isolation.
Engineering focus: Independent reference modeling, UVM-based pre-silicon verification, power-aware verification, hardware emulation and FPGA prototyping, firmware and driver bring-up against actual RTL.
What Better PPA Actually Establishes
The Assumption Worth Separating
Where the Evidence Runs Out
PPA optimization is bounded by the design it is given. Synopsys introduced DSO.ai in 2020 as a reinforcement-learning layer over the implementation flow, and announced the first 100 commercial tape-outs in February 2023. STMicroelectronics reported more than 3x PPA exploration productivity on a 7 nm FinFET Arm core run on Microsoft Azure; SK hynix reported a die-size reduction of around 5%. Those are documented results from specific projects, not a figure any design should expect to reproduce. They are also results on implementation quality, while logic and functional flaws — defects relative to intent — have remained the leading contributor to respins across two decades of industry survey data, with a substantial share traceable to specification changes rather than implementation mistakes. The 2026 picture of what AI-driven EDA tools do is accurate; the question here is which risk those capabilities retire.
Reported first-silicon success is moving the wrong way. The 2026 Siemens EDA and Wilson Research Group Functional Verification Study, published in September 2026, drew 604 qualified participants — 320 working on IC/ASIC projects and 284 on FPGA projects. Among the IC/ASIC respondents, 5% reported first-silicon success, against 14.4% in the 2024 study. Verification consumes roughly half of total project time, and most projects run behind schedule. Three qualifications belong with that number. It covers survey respondents, not AI-assisted projects specifically. It reports success on first implementation, not a count of escaped defects. And the study states explicitly that it does not establish any single factor as causal. What it supports is a narrow reading: reported first-silicon success has fallen over the same period in which implementation productivity rose, so the two are not measuring the same thing.
Generated RTL passes syntax well before it passes function. Natural-language-to-Verilog generation is the fastest-moving part of the stack, and the benchmark picture depends heavily on scale. On module-level academic suites such as VerilogEval and RTLLM, frontier models post strong pass rates. On ChipVerilog, a benchmark built from OpenCores-derived production-scale IP, two frontier models exceeded 93% syntax pass@5 while reaching roughly 37% functional pass@5 — that is, five generation attempts allowed per task — with functional correctness falling sharply on long modules. These are benchmark figures for specific models on a specific task set, not a correctness rate for production RTL. The practical risk they point at is procedural: where a team generates the testbench from the same reading of the specification that produced the RTL, a misread requirement is encoded in both the design and the check meant to catch it. LLM-aided hardware design is useful at the scaffolding layer and needs an independent oracle at the sign-off layer.
Coverage closure measures the plan, not the design space. Verification-side ML — coverage-space optimization engines such as VSO.ai, which analyze coverage and help identify gaps — reaches defined coverage goals with fewer cycles. That is a real efficiency gain. It is bounded the same way everything else is: by the model it optimizes against. If a cross between a DMA burst and a low-power entry is absent from the verification plan, coverage-driven optimization does not guarantee that the interaction will be exercised or checked, and the metric will not report its absence. Random stimulus may still happen to hit it; nothing in the measurement tells you whether it did.
Published gains are conditioned on the environment that produced them. Google’s reinforcement-learning macro-placement work, published in Nature in 2021 and later named AlphaChip, remains the most contested result in the field. Independent replication attempts — the ISPD 2023 paper by Cheng et al. and Igor Markov’s “The False Dawn” — reported that established methods matched or beat the RL approach under their comparisons. The authors’ rebuttal argues those attempts omitted pre-training and ran with roughly 20x fewer RL experience collectors (26 versus 512) and half the GPUs; Nature investigated and published an Addendum in 2024. The dispute does not show that ML-EDA results are generally irreproducible. It shows why a vendor or paper figure belongs in the project plan as a hypothesis to benchmark on your own design, not as a committed number.
Where the Unverified Properties Live
specification → RTL → synthesis → netlist → equivalence check → place and route → STA / DRC / LVS sign-off → GDSII → fabrication → first silicon → bring-up platform → bootloader → drivers → OS → application workload
Machine learning now appears at several points along that path, not one: generation and scaffolding before RTL, coverage optimization in verification, PPA optimization in implementation, pattern optimization in test, predictive analysis toward yield. The point is not that ML is confined to one segment. It is that the gains most often quoted — PPA — are produced in the implementation segment and measure implementation quality.
Two properties sit outside what those gains measure. The first is upstream: whether the RTL expresses the requirement, including requirements that changed after RTL was written or were read differently by the designer and the verification engineer. The second is downstream: behavior that only exists once software runs — boot sequencing, interrupt latency under load, DMA coherency against a real driver, power-state transitions driven by firmware rather than by a directed test.
The companion analysis to the 2026 study frames the same shift: from verifying designs toward building system confidence in software-driven silicon, with firmware-, safety- and security-related contributors to respins more visible in the data. That is a different activity from optimization and needs its own infrastructure, including running real firmware on FPGA before first silicon rather than inferring system behavior from a transaction-level model.
Three Patterns Worth Checking For
Illustrative scenarios based on common verification failure modes; not descriptions of specific Promwad projects.
Pattern 1 — State loss across a low-power transition. A block is expected to retain state across a low-power entry. In simulation the entry is driven by a directed testcase. On silicon it is driven by power-management firmware, which reaches the state machine by a different path and with a different set of pending transactions. Catching this class of defect before silicon requires explicit power intent — UPF, plus the static, dynamic and formal checks that go with it — because retention, isolation and domain shutdown are properties of the power architecture rather than of the functional RTL alone. A standard FPGA prototype does not reproduce physical power-domain shutdown. Firmware-driven tests can expose interactions missing from the existing test plan; they complement directed simulation, formal checks and power-aware verification rather than replacing them.
Pattern 2 — The mirrored specification error. An engineer scaffolds a register interface from a specification section with model assistance, then generates a SystemVerilog testbench from the same section in the same way. Lint is clean, the testbench passes, block coverage reaches target. Both artifacts encode the same reading of a write-enable qualifier. If that reading is wrong, nothing downstream of it can detect the error, because the oracle shares a derivation with the design under test.
Pattern 3 — Coverage closed, interaction unplanned. An ML coverage-targeting engine takes a block to its coverage goal in a fraction of the previous regression budget. Months later an escape turns out to be a deadlock between a DMA burst and a cache maintenance operation — a cross that was never in the coverage model. The engine did what it was asked and closed the defined space efficiently. Expanding the space is a separate engineering activity, and it has to be scheduled as one.
ASIC Verification and Pre-Silicon Engineering
Machine learning has made chip implementation faster and the resulting PPA better. Establishing that a design meets its requirements, and that firmware running against the actual RTL behaves correctly, is separate work that has to be planned and resourced. Promwad provides ASIC front-end services: HDL modeling and simulation, UVM-based pre-silicon testing, hardware emulation, FPGA prototyping on commercial and custom kits, RISC-V validation, pre- and post-silicon validation, and custom driver development.
Engineering Experience Across Silicon and Prototyping Platforms

RISC-V ASIC Verification and FPGA Prototyping
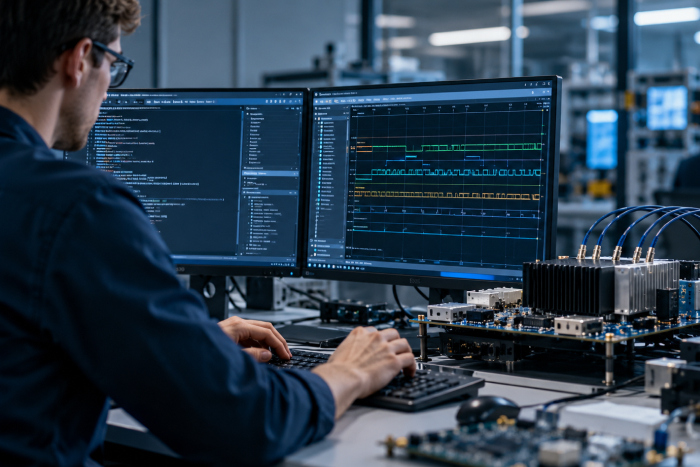
In a custom ASIC program built around a RISC-V CPU, Promwad handled validation and prototyping after the logical implementation of the circuit — the stage at which the question is no longer whether the logic can be built, but whether the system assembled from it behaves correctly.
The scope was software-facing. The team developed the BSP and bare-metal drivers for the RISC-V core, the zero-stage and first-stage bootloaders, and a Windows driver for the PCIe end-point using the Jungo framework. Bring-up tests were implemented for all SoC components, communicating over a QSPI bridge.
The verification stack spanned three distinct layers: RTL simulation in Vivado and VCS, hardware emulation on ZeBu, and FPGA prototyping on HAPS-80 together with VCU118 and HTG-960 evaluation kits and their mezzanine cards. The RTL was deployed on the AMD Virtex UltraScale+ platform, interfacing with AMD transceivers and external PHYs.
The integrated blocks were Synopsys IP — PCIe root complex, PCIe end-point, AXI-DMA, 10G MAC and 10G PCS, USB 3.0, LPDDR4, GPIO, UART — alongside a TotalPhase QSPI bridge and RISC-V cores from SiFive and Syntacore.
What that engagement illustrates is the shape of the work rather than a single dramatic find. Each of those IP blocks arrives verified against its own specification. The composition does not: arbitration between masters, coherency assumptions each block makes about the others, and the behavior of the whole under a bootloader rather than under a testbench are properties of the integrated design. Producing evidence about them requires simulation, emulation and prototyping used for what each is good at — and software executing against the actual RTL, on a platform fast enough to run it, before the design becomes a mask set.
Four Steps That Close the Gap
Step 1: Write down what each automated gate proves. Equivalence checking establishes RTL-to-netlist equivalence within the models and setup used. Static timing establishes timing at the corners run. Neither takes the requirement as an input. Teams that have this written down stop reading a clean flow report as a statement about functional risk, which is the most expensive misreading available in an AI-assisted program.
Step 2: Keep the oracle independent of the design. Any reference model, testbench or assertion set used to judge generated RTL should come from a different pass over the specification than the RTL did — ideally a different engineer, and not the same prompt. It is a cheap procedural rule, and it is the only thing that catches a mirrored misreading, which is invisible to every metric downstream of it.
Step 3: Match the platform to the question. RTL simulation gives full visibility at low throughput and is where most functional debug belongs. Hardware emulation runs orders of magnitude more cycles with signal-level visibility and fast turnaround on design changes. FPGA prototyping runs faster still and is where substantial software workloads — bootloaders, drivers, OS bring-up — become practical, at the cost of visibility and compile time. Power-domain behavior needs power-aware verification against explicit power intent, since a standard prototype does not reproduce physical shutdown. Which combination a program needs depends on design size, schedule, process node and the assurance level required; the cost of adapting production RTL to FPGA — substituting ASIC memory macros, analog blocks and high-speed I/O with FPGA-compatible equivalents — is real engineering effort and belongs in the plan rather than in the contingency.
Step 4: Treat the coverage model as a design artifact with an owner. When ML-driven closure frees regression time, some of it is worth spending on what the model does not contain: crosses between independently developed subsystems, power-state and functional-mode crosses, error and exception paths. The engine optimizes against the model. Someone still has to own the model.
Trade-Offs to Expect
Reinforcement-learning implementation versus engineer-tuned flows. RL-driven exploration covers more of the design space per engineer-hour and has produced documented PPA gains on real tape-outs. It also binds the project to a specific flow, compute budget and set of learned priors, and results may shift across nodes, foundries or tool versions. Budget for measuring the gain on your own design rather than inheriting a published figure.
Model-assisted RTL generation. Compressing the scaffolding phase — register maps, bus interfaces, boilerplate state machines — is a genuine schedule gain where an independent oracle already exists. Where it does not, generation speed is borrowed against verification effort that has to happen anyway.
Coverage optimization and where the saved time goes. Spending recovered regression cycles entirely on the next block maximizes throughput and leaves the verification plan as complete as it already was. Spending part of it on plan review is slower and is the part that addresses unplanned interactions. This is a scheduling decision, not a property of the tool.
Emulation versus FPGA prototyping. Emulation costs more per project and gives deep visibility with fast recompile — the right tool while bugs are still being found. Prototyping gives higher throughput for software execution with less visibility and longer compiles. Larger programs typically use both at different stages; smaller or simpler designs may be well served by one. The determining factors are design size, software content and schedule, not preference.
Open flows versus commercial flows. Open toolchains such as OpenROAD with ML-guided autotuners lower entry cost and make the optimization path inspectable. Commercial flows bring foundry PDK support and sign-off qualification. Which fits depends on the node, the volume and the assurance requirements — research chips and shuttle runs frequently sit on one side of that line and high-volume advanced-node products on the other.
Typical Pre-Silicon Validation Tasks
Power-Aware Verification
Power intent capture in UPF, and the static, dynamic and formal checks covering retention, isolation and domain transitions that functional RTL verification alone does not address.
Pre- and Post-Silicon Validation
Bring-up test libraries, software-based verification in ANSI C, RISC-V CPU validation, and the regression path carrying pre-silicon findings through to first-silicon debug.
Emulation and FPGA Prototyping
Hardware emulation for high-cycle-count debug with signal visibility; FPGA prototyping for software execution at throughput; plus the RTL adaptation work required to map ASIC memory macros and high-speed I/O onto FPGA fabric.
Firmware and Driver Bring-Up Against RTL
Bootloader stages, BSP and bare-metal drivers, host-side drivers, and component-level bring-up tests executed against the actual design before tape-out rather than against a behavioral model.
Independent Reference Modeling and UVM Verification
Building the functional oracle separately from the design under test; constrained-random and directed stimulus, assertion development, and coverage-model definition driven by the interactions integration will produce.
You May Be Facing This If
- PPA results from the AI-assisted flow improved measurably and the respin rate did not.
- The functional specification changed after RTL freeze and no one can state precisely which blocks absorbed the change.
- RTL that was generated or scaffolded with model assistance is being checked by testbenches derived from the same reading of the specification.
- Functional coverage closes early and escapes still appear during integration, which points at the verification plan rather than the closure engine.
- The design has multiple power domains and there is no explicit power intent description driving retention and isolation checks.
- Firmware runs against a C or transaction-level model, and its first execution against real RTL is scheduled after tape-out.
- Third-party IP blocks are treated as verified on arrival, with no composition-level verification of arbitration, coherency or shared-resource behavior.
- A vendor or paper figure for PPA or productivity is carried into the project plan as a commitment rather than as a hypothesis to measure.
Where This Becomes an Architecture Question
At this point the work is pre-silicon validation architecture: an explicit map of what each automated gate proves, an oracle built independently of the design, power intent captured and checked, and software executed against real RTL on emulation or prototyping hardware before tape-out.
Where the silicon carries a custom CPU, that path runs through FPGA and SoC design and the RTL-to-FPGA adaptation it depends on. Where the design has to boot an operating system, Linux kernel, BSP and driver engineering is the layer that turns a working netlist into a working product — and the layer where composition defects in an integrated SoC usually surface first.
FAQ
Does AI-driven chip design make silicon less reliable?
What does equivalence checking actually guarantee?
Can we use a language model to write production RTL?
What is the difference between simulation, emulation and FPGA prototyping?
How do we verify power-state behavior before silicon?
How much pre-silicon verification is enough?
Can you join a program that is already mid-flight?
Related Engineering Cases
- ASIC Verification and Prototyping (Service): RTL simulation, hardware emulation, FPGA prototyping, UVM-based pre-silicon testing, RISC-V validation, bootloader and driver development.
- FPGA Software and Linux Kernel Drivers for a 4K Frame Grabber: Framebuffer FPGA IP core development and PCIe IP core integration into a customer FPGA project: the IP-composition and driver layer where block-level sign-off stops being sufficient.
- Adapter Board for Automotive Radar over 10G Ethernet: FPGA-based high-speed sensor data transport on Xilinx ZCU102, where interface bring-up and data-path validation happen on real hardware.