


Multi-Camera Edge Robots: Synchronization, Bandwidth And Thermal Limits
Quick Overview
Check first: Exposure timing, timestamp meaning and frame identity across the cameras used together for fusion.
Budget separately: Camera-link payload, ISP throughput, memory reads and writes, and sustained processing capacity.
Validate together: Capture alignment, result age at the planner, latency percentiles and frame loss under the complete workload at the specified ambient temperature.
Where it appears: Warehouse and industrial AMRs, mobile manipulators, inspection cells, surround-view off-highway machines, docking stations, drones with onboard stereo.
Production Failure Scenario
A stereo pair agrees on a stationary pallet and disagrees on a moving one. A six-camera pipeline holds its frame rate on an open development kit and loses frames inside the sealed robot, half an hour into a shift.
Neither symptom, by itself, says anything about the perception model. Both are commonly answered by rewriting something that was never wrong — the disparity code, the detector, the calibration — because the cause sits in the capture path, and the capture path is the part of the system that rarely gets instrumented.
The first question is not what the model is doing. It is two separate questions: when did each camera observe the scene, and how old is that observation by the time the planner uses it. Those two have different causes, different measurements and different fixes, and collapsing them into one "synchronization problem" is what keeps the investigation going in circles.
Wrong Assumption
The assumption is that synchronization is a property the hardware either has or does not have: wire the sync signal, confirm it on a scope, and the cameras are synchronized.
A synchronization signal aligns whichever event the camera mode exposes. Depending on the sensor and its configuration, that may be the start of exposure, the start of readout, or the output of the frame. Even where it starts exposure, two cameras integrating for different durations observe the scene over different windows — and independent auto-exposure changes those durations frame by frame. Separately, a frame that was captured correctly can still arrive too late to be useful, which is a queueing problem rather than a timing problem, and is fixed by different means.
Three quantities have to be verified independently. A single "synchronization error" figure hides which one is failing.
Table 1 — Three quantities to verify separately
| Quantity | What It Describes | What To Verify |
|---|---|---|
| Capture alignment | Timing difference between the observations used together for fusion | Trigger-to-exposure behavior in the deployed sensor mode, exposure duration, shutter mode, row timing |
| Timestamp accuracy | How well the metadata represents the actual observation time | Timestamp source and clock domain, calibrated offset, correct frame association through the pipeline |
| Delivery latency and frame age | Time spent before the result is used by its consumer | Queue residence, per-stage execution, result timestamps, and the consumer deadline |
Frames captured together stay temporally aligned even if they finish processing at different times, provided capture timestamps survive the pipeline and frames are paired correctly. The late result may still be unusable — but it is unusable because it is old, not because it is misaligned.
Why It Fails
A shared trigger does not guarantee a shared observation window. Which event the sync signal controls is a property of the sensor and its mode, not of the link. TIER IV documents both shutter-sync and readout-sync modes on specific camera products, and Analog Devices describes the GMSL triggering and timestamping options at the link level. Where the signal does start exposure, independent auto-exposure can still put two cameras in a stereo pair on different integration windows whenever they face different lighting. Rolling shutter adds a second effect, because different rows observe different moments and the frame therefore has no single observation time.
A timestamp is useful only when its meaning is known. The Linux V4L2 buffer documentation distinguishes the timestamp clock from source flags indicating start of exposure or end of frame, and what a given driver actually reports has to be checked rather than assumed. A CSI frame-start event is not automatically the start of optical exposure. Where devices sit in different clock domains, that mapping has to be established and verified before timestamps are subtracted from one another.
Memory traffic is set by formats and intermediates, not by camera count. "1080p30" does not define a data rate until the pixel format is fixed, and the same six cameras can generate very different amounts of traffic depending on what the preprocessing path materializes. This is the measure-the-pipeline-not-the-component pattern described in AI inference latency in production pipelines, applied one stage earlier — at capture rather than at inference.
Backpressure is a buffer-ownership problem before it is a capacity problem. A capture pool and a processing queue serve different purposes. If downstream stages retain capture buffers, capture can run out of free buffers while the processing queue is still filling, and the resulting frame loss looks like a throughput shortfall that more compute will not fix.
Thermal and power limits reduce clocks, and not necessarily everywhere at once. On Jetson, power and thermal management can impose frequency limits, and which engines slow down depends on the platform, the power mode and the cooling policy. Electrical power limits can reduce clocks without an overheating event at all. The practical consequence is that stage timings validated on an open development kit do not transfer to a sealed enclosure at maximum ambient.
These interact in a way that makes the diagnosis harder than any of them alone. A capture-alignment error produces a small, motion-dependent bias that is usually attributed to calibration. A clock limit stretches a processing stage, which deepens queues, which raises frame age — and an intermittent bias that comes and goes with temperature is a problem nobody closes, because it is not a calibration error. The same coupling between thermal state and timing appears one layer downstream, in deterministic motion loops when physical AI shares an SoC, where the consequence becomes mechanical rather than visual.
Hidden System Complexity
sensor exposure → row readout → serializer → coax → deserializer → CSI-2 virtual channel → ISP → DRAM → preprocessing → DRAM → inference → DRAM → fusion and post-processing → planner → controller
Two budgets run along that path and they are calculated differently.
The link budget. For active pixels alone, 1920 × 1080 × 30 × 10 gives 0.622 Gb/s for packed RAW10; RGB888 gives 1.493 Gb/s. Transport overhead and sensor readout timing are added on top, and RAW10 may occupy a wider container once it reaches host memory. Check the complete capture configuration rather than the camera count: serializer and deserializer ports, CSI-2 lanes and rates, virtual-channel routing, supported sensor modes, and host capture and ISP limits. Virtual-channel IDs identify streams; they do not create bandwidth, and their usable count depends on the specific devices and software stack. Several cameras can share a CSI port through an aggregator, so camera count is not the same as lane-group count. NVIDIA's GMSL camera framework documentation shows how routing and lane configuration enter driver setup; verify the numbers against the BSP actually deployed.
The memory budget. List the surfaces each stage reads and writes. A full-resolution RGB FP32 intermediate occupies 24.8832 MB at 1920 × 1080, while a 640 × 640 RGB FP16 model input occupies 2.4576 MB. Materializing the larger tensor before resizing can dominate preprocessing traffic — which is the single most common reason a team concludes it needs a larger module.
Table 2 — Logical payload for two preprocessing paths producing the same model input
| Logical Payload Per Frame | Full-Resolution Intermediate | Fused Preprocessing |
|---|---|---|
| Capture write of NV12 | 3.1104 MB | 3.1104 MB |
| Full-resolution conversion, read + write | 27.9936 MB | Included below |
| Resize and normalization, read + write | 27.3408 MB | 5.5680 MB |
| First read of the model input | 2.4576 MB | 2.4576 MB |
| Total per frame | 60.9024 MB | 11.1360 MB |
| Six cameras at 30 fps | 10.9624 GB/s | 2.0045 GB/s |
Calculation scope. MB and GB use decimal units. Each listed surface is assumed to be read or written once per operation. These are logical payload totals, not measured DRAM bus traffic or whole-system bandwidth; cache reuse, stride, tiling and transaction behavior change physical traffic. Sensor RAW handling, other ISP accesses, model weights and intermediate activations, display, recording and middleware copies are excluded. Both paths start from the same tightly packed 1920 × 1080 NV12 surface and produce the same 640 × 640 RGB FP16 tensor.
The calculation identifies an intermediate worth removing. It does not predict a latency improvement. Verify fused-kernel support, image quality, color conversion and numerical equivalence on the chosen platform; a hardware scaler can also resize before tensor conversion where a fully fused path is unavailable. DMA-BUF buffer sharing can avoid redundant copies between compatible devices, but zero-copy still involves reads and writes — the ISP writes pixels and preprocessing or inference reads them. Compare profiling results against sustained bandwidth under the actual concurrent workload; there is no universal utilization threshold that predicts failure on every memory controller.
Failure Patterns
Scenario 1. A stereo pair produces acceptable depth on static targets and motion-dependent error on crossing ones, with frame age comfortably inside budget. The sync signal measures correct. The two views face very different lighting and run independent auto-exposure, so their integration windows differ. The disparity algorithm is correct and the answer is wrong, because the two images do not describe the same instant.
Scenario 2. A six-camera pipeline runs clean on an open development kit and loses frames in bursts inside the production enclosure, starting well into a sustained run. Average CPU load stays moderate throughout. Clock or throttle telemetry logged on the same timeline shows a frequency limit taking effect; stage timings stretch, a downstream consumer holds capture buffers longer, and capture runs out of free buffers.
Scenario 3. Multi-view fusion is stable on the bench and drifts under load. Capture alignment is unchanged. Frames are being associated by the time they arrive in userspace rather than by their capture timestamp and sequence number, and queue residence varies enough under load that the matching window starts selecting the wrong combinations.
Edge AI and Multi-Camera Perception Engineering
Multi-camera failures in edge robots — motion-dependent depth error, drifting fusion, bursty frame loss under sustained load — are capture-path and system-architecture problems. Closing them takes separate budgets for capture alignment and frame age, verified timestamp semantics at the driver level, a memory model built from surfaces rather than from camera count, and validation inside the production enclosure at the specified ambient. Promwad designs the full path: carrier boards and SerDes capture, V4L2 and ISP bring-up, edge AI deployment on NVIDIA, Qualcomm and NXP platforms, and the thermal design underneath.
Engineering Experience Across Edge AI, Vision and Robotics Platforms
Worked Example — Two Exposures
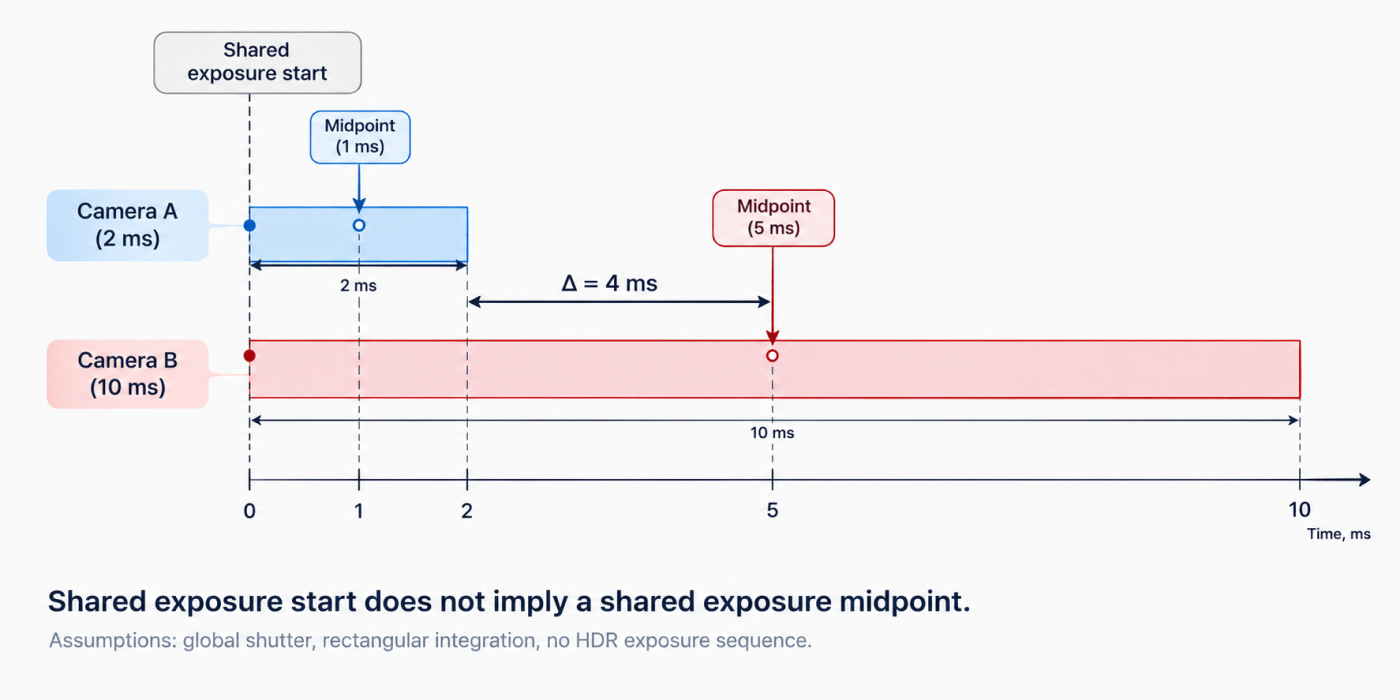
Assume a global-shutter sensor mode in which a common trigger starts both exposures. Camera A integrates for 2 ms and camera B for 10 ms. For rectangular integration with uniform temporal weighting, their approximate exposure midpoints fall 1 ms and 5 ms after the trigger: a 4 ms difference. At 1 m/s relative motion, that represents 4 mm of scene displacement.
This is a calculated example, not a measurement from a Promwad project. Converting the displacement into stereo depth error also requires the baseline, focal length, range and direction of motion — and depth error grows with the square of range for a fixed baseline, so the same temporal difference that is harmless close in can be unacceptable further out.
Coordinating exposure duration within a fusion group improves temporal consistency, at the cost of image quality when the views face very different lighting; different gains may still be useful. Exposure metadata helps estimate sampling time but cannot undo motion blur or recover detail lost during a long exposure. Rolling shutter needs an additional model using the actual sensor mode, row interval and readout direction. Global shutter removes the row-by-row offset, while exposure duration and delivery latency still need checking. HDR modes require their own timing model.
Solution Approach
Step 1: Establish what the timestamp means before trusting it. Check what the deployed driver reports for each camera, not what the standard permits. Keep the original timestamp and frame sequence through the ISP, preprocessing, inference and ROS 2 messages, and associate exposure metadata with the frame it actually affected — a control written now may take effect in a later frame. Validate the interpretation with a calibrated optical timing reference visible to all relevant cameras; an ordinary display counter has its own refresh and scanout timing and is not automatically a sub-millisecond reference. This work belongs in camera-driver and BSP bring-up, before timestamp assumptions are baked into the fusion code.
Step 2: Build the memory model from surfaces, then measure it. For each camera, write down every read and write between the sensor and the accelerator with the pixel format and precision at each hop, multiply by frame rate, and sum across cameras. Use the result to identify intermediates worth removing rather than to predict a latency figure, then confirm against profiling under the actual concurrent workload. Where even a well-tuned software path cannot hold the timing, an FPGA frame-grabber architecture can align streams or reduce data before they reach the SoC.
Step 3: Make ownership and frame age explicit. Trace when each stage acquires and releases a buffer. On asynchronous accelerators, returning a buffer before processing finishes risks corruption, while holding it too long stalls capture. Track queue residence and frame sequence gaps alongside stage execution time. At 30 fps the frame period is about 33.3 ms, so a few frames of waiting can consume the available age budget. Set a maximum acceptable age and define which frames — or which complete fusion groups — to discard when it is exceeded; dropping one camera independently can leave an unusable stereo pair. Where the result feeds motion, those limits come from the same place as the latency budget of the industrial control system.
Step 4: Test sustained performance at the shipping thermal limit. Use the production enclosure, the intended power mode and the maximum specified ambient. Run every required camera together with perception, recording, networking and other concurrent functions. Continue until temperatures and performance stabilize, then cover the required duty cycle — a fixed ten-minute or one-hour run is not sufficient evidence by itself. Log temperature, power and available clock or throttle telemetry on the same timeline as latency and frame loss. If cooling is the constraint, review the module-to-chassis conduction path, airflow and power budget with the mechanical design: carrier-board integration and thermal analysis need the camera workload as a design input. On a Jetson system-on-module, DRAM sits on the module, so a carrier-board revision does not reroute that memory interface.
Acceptance criteria should name capture alignment per fusion group, result age at the planner, latency percentiles and deadline misses, delivered frame rate and dropped-frame bursts — compared between cold and thermally stable operation. A low average CPU load does not rule out a saturated memory path, a blocked consumer or a reduced clock limit.
Real Trade-Offs
Start the trade from the failing measurement. Motion-dependent disagreement with acceptable frame age points toward exposure timing, shutter behavior or calibration. Growing frame age with preserved capture alignment points toward processing and queues. Late frame loss accompanied by clock changes calls for a power or thermal investigation. Choosing the fix before identifying which of the three is failing is how teams end up optimizing a model that was never the constraint.
Global shutter versus rolling shutter. Global shutter removes the row-by-row exposure offset, which matters most where a camera is measuring a moving object rather than classifying it. It typically costs more, and the in-pixel storage node costs fill factor. The choice depends on the task and the tolerable error, not on a rule that every obstacle-detection camera must be global shutter. Mixing both in one robot is normal — the fusion code then has to know which sensor it is reading and carry the readout model with the frame.
Coordinated versus independent exposure. Sharing exposure duration across a fusion group makes capture alignment predictable and makes one view noisier or darker when the views face very different lighting. Carrying per-frame exposure metadata through the pipeline is worthwhile either way, because it lets the fusion stage estimate sampling time instead of assuming it.
Resolution and frame rate. Reducing either lowers link payload, ISP load, memory traffic and compute together, which is the cheapest capacity available. It can also reduce small-object detection range or stereo quality. Validate the change against the perception task, not against throughput alone.
Deeper queues versus fresher data. More buffers can absorb a bounded burst. They cannot fix a consumer that is consistently slower than the arrival rate, and they can make results too old for the planner. Processing can be staggered after capture while retaining frame identity, which may smooth resource demand — but changing capture phase is a different decision, because it changes when the scene is observed.
FPGA preprocessing. It is useful when it can align streams or reduce data before they reach the SoC, and it can avoid intermediate transfers. It does not correct unequal exposures by itself and does not by itself make the end-to-end robot deterministic; final data still need transport and storage wherever the architecture requires them. The same reasoning is laid out for FPGA-based vision and event cameras in real-time robotics perception.
Active versus passive cooling. A fan buys thermal headroom and brings an ingress-protection problem, an acoustic problem, a new failure mode and a maintenance item. Conduction to the chassis is usually the first thing to try, and deciding this during board and enclosure design rather than during integration testing is the difference between a mechanical revision and a respin.
Typical Multi-Camera Engineering Tasks

Capture Path And Driver Bring-Up
SerDes integration, CSI-2 lane and virtual-channel routing, V4L2 and ISP configuration, and buffer sharing between capture, preprocessing and inference.
Memory And Pipeline Optimization
Surface-level traffic modeling, hardware-accelerated resize and conversion, precision and layout selection, and buffer ownership with an explicit frame-age policy.
Carrier Board And Thermal Design
Carrier-board integration for edge modules, conduction-path design, airflow and power budget, and thermal analysis against the specified maximum ambient.
Sustained-Load Validation
Full-camera-count test plans inside the production enclosure, with temperature, power, clock telemetry, latency percentiles and frame loss logged on one timeline.
Capture Timing Verification
Establishing what the sync signal controls in the deployed sensor mode, verifying timestamp source and clock domain, and validating the interpretation against a calibrated optical reference under production lighting.
Qualifying Symptoms
- Depth or fusion error is acceptable on static targets and grows with relative motion, while frame age stays inside budget.
- The synchronization signal measures correct, and perception accuracy still changes with scene lighting in a way calibration cannot explain.
- Frame drops appear in bursts well into a sustained run, with average CPU load moderate throughout.
- Results reach the planner intact but late, and the latency grew without any change to capture.
- Frame association uses userspace arrival time, and the matching window had to be widened at some point to stop losing pairs.
- Adding a camera increases end-to-end latency on the existing cameras, not only on the new one.
- Preprocessing materializes a full-resolution floating-point intermediate before resizing.
- The test matrix was run on an open development kit, at partial camera count, or for a fixed short duration rather than to thermal stability.
Solution Context Link
At this stage the work is capture-path and system architecture rather than another pass on the perception algorithm: verified timestamp semantics, separate limits for capture alignment and frame age, a memory model built from surfaces, and acceptance criteria that include the thermal operating point.
The platform context sits in edge AI engineering, where inference is shaped to share a platform with several other real-time tenants, and in robotics engineering at the system level. For NVIDIA-based platforms, NVIDIA-powered robotics development is where the capture path, ROS 2 and the motion budget are engineered together. Where the product is an inspection or quality-control station rather than a mobile robot, the same discipline sits inside industrial machine vision engineering.
Two adjacent contexts are worth naming. In vehicles and off-highway machines the same path is measured end to end as glass-to-glass latency in real vision pipelines, where stitching and display add stages the robotics case does not have. And in warehouse fleets, moving perception and routing to the edge is what raises camera count per robot in the first place. When selecting a platform for a camera-heavy product, compare candidates on sustained behavior rather than peak figures.
Promwad Proof — Related Engineering Work
Multi-Camera Edge AI On NXP Platforms
Promwad's on-device multi-camera edge AI reference design combines the NXP i.MX 95, the FRDM i.MX 8M Plus board and an Ara240 discrete accelerator. Built in-house, it runs multi-camera video analytics alongside a local language-model agent, with ISP controls and CAN indication; natural-language commands switch camera views and adjust the image pipeline while the system runs locally. The same setup has been shown publicly at NXP Tech Days.
Jetson Robotics With Industrial Networking
The Jetson robotics platform with industrial protocols combines NVIDIA compute, camera and LiDAR inputs, ROS 2 and a Hilscher industrial-network controller. Its architecture includes FPD-Link III camera inputs and runs the industrial protocol stack on the Hilscher controller, showing how perception and machine communication are integrated across those components.
Service Robotics On Qualcomm RB3 Gen 2
The Qualcomm-based service-robot engineering kit brings together camera and LiDAR navigation, ROS 2 and EtherCAT motor control. The associated reusable robotics software stack describes the motion firmware, ros2_control integration and Yocto-based deployment: navigation commands become drive setpoints, while encoder feedback returns to ROS 2 for odometry and monitoring.
Related reading, adjacent rather than equivalent: a real-time rail multi-sensor platform (FPGA and multi-sensor fusion in a different device class) and high-speed OpenGear cards for multi-camera broadcasting (sustained multi-stream video transport). Neither is evidence of robotics capture synchronization and should not be presented as such.
FAQ
Does Hardware Frame Sync Guarantee Synchronized Images?
How Much Capture Misalignment Can A System Tolerate?
Where Should The Frame Timestamp Come From?
Does Zero-Copy Eliminate Memory Traffic?
Will More Buffers Stop Frame Drops?
Global Shutter Or Rolling Shutter For A Robot?
Does Moving Capture To An FPGA Solve This?