


From Ownership to Service: Engineering Reliable On-Demand Mobility
Quick Overview
Problem: A mobility fleet with a working app and road-legal vehicles loses bookable availability to unlock failures, parked-vehicle no-starts, stalled update campaigns, and faults that surface late.
Common failure points: Access credentials whose validity and revocation policy was never written down, radio power-saving settings chosen for telemetry rather than for commands, 12 V energy budgets derived from an owner’s usage pattern, update campaigns scheduled without vehicle availability as a constraint, and user state that persists from one driver to the next.
Where it appears: Car sharing and free-floating fleets, vehicle subscription programs, ride-hailing fleet platforms, corporate pool fleets, micromobility and cargo-bike sharing, and OEM mobility divisions putting consumer vehicle platforms into service fleets.
Engineering focus: Separating the command path from the telemetry path, digital-key lifecycle with explicit expiry and revocation policy, 12 V budgeting against the fleet’s measured parking data, update orchestration that treats availability as a constraint, and remote diagnostics through the vehicle’s secure gateway.
An Illustrative Failure Scenario
The scenario below is a composite drawn from recurring patterns in shared-fleet programs. It is not a single client engagement, and the figures are illustrative rather than measured.
A mobility operator launches on schedule. The app books, unlocks, and bills within seconds. Depot acceptance testing on a sample of vehicles passes every metric it is given.
Some weeks into operation, the picture changes. A share of the fleet is unbookable on a typical morning — not damaged, not reserved, simply not responding in time. Vehicles in underground garages unlock slowly, or not at all. No-start events cluster after long parking intervals. An update campaign scheduled for a low-demand window completes on most of the fleet and leaves a tail that operations halts rather than chases.
Each of those symptoms arrives at the operator as the same thing: a vehicle that did not become available. What they have in common is not a root cause — it is that the evidence needed to separate them was never designed into the system. Determining the actual cause in any individual case requires vehicle-side instrumentation that, in most launches, does not exist yet.
Teams typically assume: if the vehicle works, the telematics unit reports, and the app unlocks it on the bench, the fleet will behave the same way at scale.
Where that breaks down: shared operation changes several subsystem assumptions at the same time — how parking intervals are distributed, how often and how quickly the vehicle must answer a command, how many different credentials it accepts in a week, when it can be taken out of service, and how a fault becomes visible. Each of those is a different subsystem, and from the outside several of them fail the same way.
The Wrong Assumption
The assumption behind most of these launches is that on-demand mobility is a commercial model layered on an unchanged product: add a telematics unit, an app, and a backend, and the car becomes a service.
That skips the part of the vehicle that decides whether the service works. A privately owned car is engineered around a durable owner identity, a usage pattern that recharges the 12 V battery regularly, an update process with a user who is informed and waits, and a feedback loop where the owner notices a fault and books service. Shared operation changes each of those inputs. Some of the resulting problems are genuinely architectural and need a design change. Others are configuration, software defects, or integration gaps and can be closed without one. The engineering value is in telling those apart early, which is what the rest of this article is about.
Why Availability Is Lost
The command path and the telemetry path have different requirements, and are often built as one. This matters most where the access path depends on a low-power cellular link — typically aftermarket tracking and access units rather than OEM telematics control units, which are usually specified differently. In LTE-M and NB-IoT, Power Saving Mode lets the module stop monitoring paging entirely, so a mobile-terminated command cannot be delivered until the device sends uplink or its periodic tracking-area update falls due; extended DRX keeps the device reachable but lengthens the paging cycle, with the maximum cycle reaching tens of minutes for LTE-M and longer for NB-IoT (Nordic Semiconductor, PSM documentation). Whether a command waiting during PSM is held and delivered on wake, or lost, depends on network support, buffering retention, and whether the application retries — it should not be assumed. A power profile tuned for a tracker and a command target measured in seconds are different design points, and reconciling them is a specification decision rather than something to discover in the field.
Vehicle subsystems persist user state by design. Bonded Bluetooth devices stay in the head unit’s list, and the capacity of that list varies by platform rather than following a single industry figure. Contacts synced by a previous driver can remain in the infotainment unit. Seat, mirror, and drive-mode profiles carry over. In an owner’s car this is a feature. In a shared vehicle it is a privacy exposure and a support ticket, and clearing it reliably between bookings depends on whether the platform exposes a user-session concept that can be created and torn down. The same identity question runs through the whole data chain, which is why data governance in software-defined vehicles is an architecture decision rather than a policy document.
Connectivity assumptions are being revised under the network transition. European operators are retiring 2G and 3G on uncoordinated national timetables. A study published for the European Commission in May 2026 estimated that, without intervention, around 64 million vehicles in the EU could lose eCall functionality, and recommended that Member States preserve at least one circuit-switched network until at least 2030 — a recommendation in a Commission-commissioned study, not an established obligation (European Commission, Shaping Europe’s digital future). On the vehicle side, Delegated Regulation (EU) 2024/1180 moves eCall onto packet-switched networks through the type-approval route: from 1 January 2026 the requirements apply to new type approvals and to extensions of existing approvals, and from 1 January 2027 to the registration and entry into service of new vehicles in scope (EUR-Lex, Reg. (EU) 2024/1180). Neither date requires retrofitting the existing parc. For a fleet operator the practical consequence is narrower and more immediate: aftermarket telematics and access units in a mixed-age fleet may depend on networks with announced shutdown dates, and that needs a per-vehicle migration plan.
Update management in a fleet has constraints the regulation does not remove. Where a manufacturer executes software updates that affect type-approved characteristics after registration, EU type-approval law requires compliance with software-update requirements introduced into Regulation (EU) 2018/858 by Delegated Regulation (EU) 2022/2236, with staged application (EUR-Lex, Reg. (EU) 2022/2236); UN R155 is carried into EU type approval through Regulation (EU) 2019/2144. UN R156 requires a Software Update Management System, including that the vehicle be in a state where the update can be executed safely and that the user be informed, and provides for restoring the previous version or transitioning to a safe state in the event of a failed update — which is not the same as a universal automatic rollback requirement (UNECE, UN Regulation No. 156). Fleet operation adds a constraint on top of those obligations rather than replacing them: a vehicle that is mid-booking, undercharged, or slow to return to service after an update is inventory that is not earning. Scheduling against availability is an engineering requirement the regulation does not address, and it sits between the update pipeline and the fleet backend. The pipeline-side discipline is covered in secure OTA update pipelines.
Driver fault reports are not a reliable primary signal. Some operators run structured return forms, photo capture, and pre-trip checks, and those are worth having. But driver reports can be incomplete, inconsistent or delayed, so they should be complemented by vehicle telemetry and diagnostics rather than relied on alone. The fleet’s dependable fault visibility is what the vehicle itself exposes: stored diagnostic trouble codes read remotely through the vehicle’s secure gateway, telemetry thresholds, and whatever sensing exists for cabin state and damage. Widening that set is a design decision taken before launch, because it determines whether a vehicle is withdrawn from inventory by the system or by a customer complaint.
Hidden System Complexity
The common mistake in debugging these fleets is to draw one linear chain from the backend to the vehicle. There are at least two distinct paths, and they fail independently.
Remote command path: booking backend → mobility API → cellular link to the telematics unit → vehicle gateway → body control / immobiliser
Local access path: credential provisioned to the phone → phone to vehicle over BLE, UWB, or NFC → access controller → vehicle gateway → body control / immobiliser
The short-range radios are not a mandatory stage of a cloud-initiated command, and a cloud link is not required for a local unlock once a credential is in place. Energy supply, diagnostics, and update state are enabling conditions across both paths rather than sequential steps in either: a sagging 12 V rail or an in-progress update can prevent a door opening without appearing anywhere in the command sequence.
This is why a single operator-facing symptom — the vehicle did not open — needs vehicle-side evidence before it can be attributed. A telematics unit in a deep power-saving state, a credential outside its validity window, and a brownout during the access handshake all produce a failed booking and a vehicle that looks healthy an hour later.
The electrical architecture adds a second axis. Which domain owns the access function determines what has to stay awake between bookings. If the unlock path runs through a central gateway, that domain’s standby consumption sets the floor. If the access function sits on a dedicated low-power controller with its own wake path, the floor is far lower. That is the same partitioning argument that drives centralized versus zonal ECU design in software-defined vehicle programs.
Four Failure Patterns
Pattern 1 — No-Starts After Long Parking Intervals
Worked as a budgeting example rather than a specification: take a 60 Ah starter battery and choose an allowance of 20% of nominal capacity — 12 Ah — as the energy the fleet is willing to spend between charge opportunities. That 20% is a design allowance selected for the example, not a physical damage threshold; real limits depend on battery chemistry, age, temperature, state of charge at the start of the interval, and the manufacturer’s own specification.
| Standby current (illustrative) | Allowance consumed in 3.5 days | Time to consume 12 Ah |
|---|---|---|
| 50 mA | 4.2 Ah | ≈ 240 h ≈ 10 days |
| 110 mA | 9.2 Ah | ≈ 109 h ≈ 4.5 days |
A Thursday-evening to Monday-morning interval is about 3.5 days, so at 110 mA it consumes roughly three quarters of the chosen allowance and does not by itself reach it. The failures happen where the starting conditions are worse than the example: a battery that began the interval partly discharged after a run of short urban trips, reduced effective capacity at low temperature, an aged battery, or an interval longer than a weekend. The engineering point is that the allowance is consumed much faster than an owner’s usage pattern would predict, so the margin that absorbs those conditions is gone. Key-off current figures in the 25–50 mA range and module sleep times of 20–30 minutes after lock are commonly cited, but both vary by vehicle and by configuration and should be measured on the target platform rather than assumed.
Pattern 2 — Unlock Failures That Cluster by Parking Location
A vehicle parked below ground may have no usable cellular path, so a cloud-initiated unlock cannot reach it. A credential already held by the phone can work over a short-range radio instead — but only within whatever local validity the credential was issued with.
Two mechanisms are often conflated here and should be kept separate. Expiry is local and time-based: a credential can stop being accepted by the vehicle without the vehicle having received anything. Revocation depends on the vehicle receiving updated information. Credential policy is managed centrally and enforced by the vehicle; if revocation information cannot reach the vehicle through an authorised channel, access may remain valid until the next synchronisation or local expiry. That channel is not necessarily the vehicle’s own cellular link — the Car Connectivity Consortium’s model covers reconnection of either the vehicle or the phone, as well as vehicle-side controls (Car Connectivity Consortium). Short validity reduces exposure from an early-terminated booking and increases failures in poor coverage; long validity does the reverse.
The radio roles should also be kept distinct. BLE provides the low-power link that initiates secure communication, but link establishment alone does not establish that the phone is physically near the vehicle; UWB secure ranging is what the Car Connectivity Consortium associates with relay-attack mitigation, and NFC provides tap-based access at the door (Car Connectivity Consortium). NFC access with a depleted phone battery depends on the device supporting a power-reserve mode and is not a general property of every NFC-equipped handset.
Pattern 3 — Update Campaigns That Fragment the Fleet
Vehicles mid-booking skip the window. Vehicles parked with insufficient 12 V headroom should not start an install. Vehicles that complete may return to service slower than the booking system’s availability timeout and be taken out of inventory. The fleet ends up on two software versions with no clean path to converge, and the next campaign must handle both.
Pattern 4 — User State That Survives the Handover
A driver reports seeing a previous user’s phone or contacts, or finds personalisation applied that is not theirs. The session was never torn down, or the only available teardown is a full infotainment reset that exceeds the turnaround window and gets skipped.
Shared-Fleet Vehicle Electronics Engineering
Availability problems in on-demand fleets are often attributed to the app or the backend, while the evidence needed to locate them sits on the vehicle side. Separating the ones that need a design change from the ones that are configuration, software defects, or integration gaps is the first piece of work. Promwad develops telematics and access electronics, embedded vision platforms, connectivity stacks, and cloud fleet services for automotive and transportation products — including a car-sharing access system with multi-fleet cloud administration and OTA firmware update.
Engineering Experience Across Automotive and Connectivity Platforms
Case Fragment: An Access and Fleet-Management System for a European Car-Sharing Operator
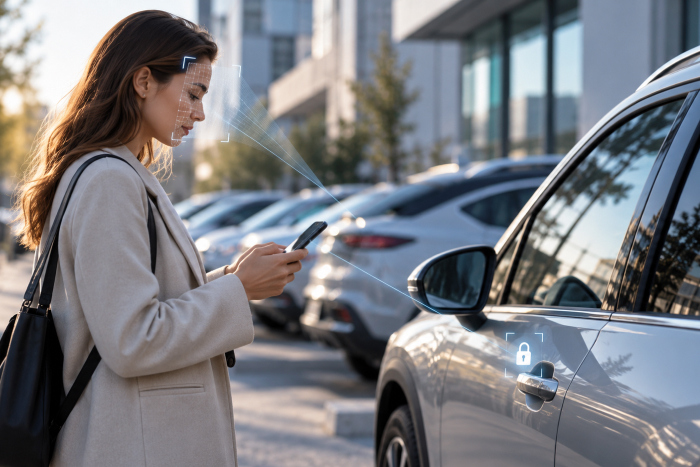
The client was a European car-sharing company. The goal was a hardware and software product with facial recognition to control and monitor access to shared vehicles and restricted areas — which is the access and identity problem described above, taken from the vehicle side rather than from the app.
The system Promwad designed has three parts. The client device is a smart camera built on an NXP i.MX 8M Plus applications processor with an integrated neural processing unit and a single MIPI CSI camera. Firmware was built on a Yocto Linux image, with on-device facial recognition, tampering detection, and OTA firmware update. The cloud side is a service prototype on Google Cloud Platform that administers multiple car-fleet companies, their devices and their users, exchanges data with an installed fleet of devices in real time, retrieves footage of critical events, collects device and client metrics, and distributes OTA firmware updates. A mobile app handles user registration and status.
Two details matter for a mobility operator. First, the identity database stored facial templates rather than raw facial photographs. These templates remain biometric personal data and require appropriate protection — the design choice reduces exposure, it does not remove the obligation. Second, fleet, device and user administration were brought into one prototype platform, providing a common foundation for managing access rights, rather than three separate integrations stitched together later.
Project stage: the engineering team completed the proof-of-concept phase and built and tested the MVP, reaching recognition accuracy above 99% at up to 16 frames per second under the project’s test conditions. Manufacture and installation in the customer’s vehicles was the planned next step. These are PoC and MVP results, not figures from a deployed production fleet.
Full project detail: Access control system with facial recognition for car sharing
How to Approach It
Step 1: Specify the command path against a stated latency target, separately from telemetry. Telemetry tolerates long sleep intervals. A command path does not, and where it shares a low-power radio its reachability is bounded by the paging configuration. In many designs the better answer is to take the network off the critical path for unlock: provision a credential to the phone at booking time and use the short-range path, keeping the cellular link for provisioning, revocation, and telemetry. That converts a coverage problem into a credential-policy problem, which is easier to reason about — but it is a trade, not a removal of risk, and it only works if the credential policy in Step 2 is sound. The stack work lives in automotive connectivity engineering.
Step 2: Write the credential lifecycle down, with expiry and revocation as separate decisions. Local validity duration; which channels are authorised to deliver revocation information and how often; behaviour when a booking is terminated before the credential expires; behaviour when the vehicle has not synchronised within the expected interval; whether an unknown-state credential fails open or closed; and where credentials are issued and terminated centrally. These are a small number of explicit decisions that determine both fraud exposure and the share of bookings that fail in poor coverage. Make them at architecture time rather than inheriting a middleware default.
Step 3: Derive the 12 V budget from the fleet’s measured parking data, not the average. Take the actual distribution of parked intervals from telemetry, including the tail, together with the state of charge at the start of those intervals and the frequency with which the electronics are woken. Size the standby allowance against the worst realistic combination of interval length, starting charge, wake frequency, and ambient temperature for the fleet’s operating region, then verify by measurement on the target vehicle after all modules have entered sleep — the settling time varies by platform. Where the budget does not close, the fix is often architectural: give the access function its own low-power domain and wake path rather than keeping a gateway domain awake.
For scale, Promwad’s internal R&D platform for exterior vehicle access holds under 100 µA in deep sleep while waking on motion, with a gesture decision returned within 120 ms and face verification above 99% for two enrolled users under defined test conditions. That figure is the sleep current of that specific access platform, measured on its own hardware — it is not the standby draw of a complete always-reachable vehicle access and telematics stack, and the two should not be compared directly. It is cited to show what an independently power-managed access domain can achieve, not as a fleet budget.
Step 4: Treat the update campaign as a scheduling problem on top of the regulatory requirements. Availability windows per vehicle, staged rollout with a canary group, a minimum 12 V state-of-charge gate before install, a bounded and monitored return-to-service time, a defined failure path — restoring the previous version or transitioning to a safe state, per the applicable requirements — and a per-vehicle record sufficient for the SUMS audit trail. A campaign that cannot report which vehicles are on which version, and why, is not finished.
Step 5: Build the diagnostic path so it does not depend on driver reports. Remote diagnostic sessions run through the vehicle’s secure gateway using whatever interfaces the platform supports. In practice that means UDS over CAN, UDS over DoIP, or both: a DoIP gateway can route diagnostic requests to ECUs that themselves communicate over CAN, so the transport available at the vehicle boundary and the transport used by a given ECU are separate questions. Add telemetry thresholds for failures that do not set a code, and explicit sensing for conditions a return form will not reliably capture — cabin state, impact events, charge-port state on EVs.
If availability reporting counts a vehicle as available whenever it is not booked and not flagged damaged, it is measuring something else. The unreachable, the undercharged, and the mid-campaign are all inside that number.
Real Trade-Offs
Command reachability versus standby current. A short paging cycle gives predictable command latency and costs standby current every parked hour. A longer cycle or deep power saving protects the battery and makes the vehicle slower or unreliable to command. Credential-based local unlock is the architectural way out of the direct trade, at the cost of taking on credential-lifecycle complexity.
Long local credential validity versus revocation latency. Long validity keeps vehicles openable in garages and dead zones and widens the window in which a terminated booking’s credential may still be accepted locally. Short validity inverts both. Fleets with significant underground parking usually need longer validity plus a compensating control, rather than shorter validity.
Aftermarket retrofit versus OEM-integrated access. A retrofit unit deploys across mixed model years and is often the practical route for an existing fleet, though not the only one — some operators negotiate OEM interface access, and some buy fleet-specified vehicles. Aftermarket integration is not inherently unapproved: UN R162, for example, provides for the approval of immobilisers and of vehicles with immobilisers fitted (EUR-Lex, UN Regulation No. 162). What it does need is a vehicle-specific assessment of power management, control interfaces, and applicable approval requirements, since the status of any particular integration depends on the device, the installation method, and the rules that apply to it. Keeping a function inside the vehicle avoids that assessment for the function itself, but does not by itself settle the approval position of the surrounding system, and it makes the operator dependent on the OEM interface.
Low-power radio versus higher-throughput radio. LTE-M and NB-IoT are well suited to telemetry and do support firmware update over the air; whether they suit a given fleet’s updates depends on image size, available throughput, coverage, and how long a delivery may take. A multi-hundred-megabyte payload over a narrowband link is a scheduling problem, not an impossibility. Standardising on one module across telemetry, command, and update is a legitimate simplification that is paid for in one of those three.
Richer per-trip data versus data minimisation. Location traces tied to an identified driver are among the most useful operational data a fleet holds and among the most sensitive. Retention, aggregation boundaries, and the controller relationship between operator and OEM belong in the logging architecture, because they are difficult to retrofit onto a pipeline that already collects everything.
Typical Engineering Tasks

Connectivity Architecture and Module Selection
Separating command and telemetry paths, setting power-saving parameters against a stated command-latency target, module and radio-access-technology selection across mixed-age fleets, and planning migration off sunsetting networks.
Vehicle Access Electronics and Credential Lifecycle
Short-range access controllers as an independently power-managed domain, credential issuance, expiry and revocation policy, secure element integration, and server-side credential management.
Telematics ECU Development
Hardware and firmware for tracking and diagnostic units, GNSS integration, CAN and Ethernet vehicle interfaces, and backend and CRM integration.
Fleet Updates & Diagnostics
SUMS-aligned campaign orchestration, staged rollout and defined failure paths, remote diagnostics through the vehicle’s secure gateway, and telemetry-driven withdrawal from inventory.
You May Be Facing This If
- A measurable share of the fleet is unbookable on a typical morning for reasons that resolve without intervention.
- Unlock failures cluster by parking location rather than by vehicle.
- No-starts correlate with parked duration, starting state of charge, and ambient temperature rather than with battery age alone.
- An update campaign leaves a tail that cannot be converged without a depot visit.
- Drivers report seeing a previous user’s phone, contacts, or profile settings.
- Faults are found at scheduled service, and customer complaints are the first signal for anything that does not set a code.
- The fleet includes telematics or access units dependent on networks with announced shutdown dates, with no per-vehicle migration plan.
- Availability reporting and the actual bookable-vehicle count diverge, and the gap cannot be reconciled from available data.
Where It Becomes a System Architecture Problem
At this stage the work is subsystem analysis and, where justified, subsystem redesign — not another integration pass against the backend. In practice: a command path specified against a latency target, a written credential lifecycle, a 12 V budget derived from measured parking data, update orchestration that treats availability as a constraint, and a diagnostic path that does not depend on driver reports.
The platform-level context sits in software-defined vehicle engineering, and the device level in ECU and embedded platform design. For fleets inside a certification scope, the process side runs through ASPICE software and hardware development, and credential storage, secure boot, and revocation handling through embedded security engineering. Where positioning accuracy is the binding constraint, the hardware-side requirements are set out in multi-constellation GNSS integration.
Electric fleets add an open question worth naming rather than claiming to have solved. ISO 15118 Plug and Charge credentials are associated with the vehicle, while a shared fleet needs charging cost attributed to whoever had the booking — so the reconciliation has to happen in the operator’s backend rather than at the charge point. Promwad’s work on cloud-based charging station software is relevant as evidence of moving charging protocol handling off the station hardware — OCPP for infrastructure communication, TLS for transport security, and ISO 15118 Plug and Charge processing executed on a cloud server — rather than as a delivered implementation of driver-level cost allocation.
A second in-progress engagement sits on the connectivity and positioning side: an ECU-based vehicle tracking system for cargo-bike fleets, built for manufacturers, sharing operators, and riders as separate user groups. The constraints that shaped it are the ones shared fleets hit — much of the installed tracker base still depends on 2G and 3G networks being retired in Europe, and conventional trackers do not give the positioning accuracy needed in dense urban traffic. The device is planned around 5G connectivity with GNSS supporting Galileo, including the High Accuracy Service, together with applications for operators and riders. Those are design intentions for a project still in development, not demonstrated field results. Galileo HAS provides free high-accuracy corrections (EU GNSS Service Centre), but achieving metre-level positioning in dense urban environments also requires a compatible receiver, correct handling of the correction stream, and validation in the target environment — and “free corrections” does not mean the absence of connectivity and operating costs.
FAQ
Why do unlock failures cluster in underground garages?
What actually causes 12 V failures in car-sharing fleets?
How is an update campaign different for a fleet?
Does the 2G and 3G shutdown affect fleet vehicles that are only a few years old?
How do you clear the previous driver’s data between bookings?
We have launched and are losing availability. Where do you start?
Related Engineering Cases
- Access Control System with Facial Recognition for Car Sharing: Built for a European car-sharing company: smart-camera devices on NXP i.MX 8M Plus with NPU, a GCP service administering multiple fleets, users and devices, mobile app, and OTA firmware update. PoC completed, MVP built and tested.
- AI Camera Platform for Exterior Vehicle Access: Internal R&D platform: gesture and face-based access on an automotive-grade SoC, deep sleep under 100 µA for that platform, ASPICE CL2 alignment from the architecture stage.
- ECU-Based Vehicle Tracking for Cargo Bike Fleets: In-progress telematics ECU for sharing operators, manufacturers and riders, planned around 5G and Galileo-capable GNSS with fleet and CRM integration.
- Software for EV Charging Stations (ISO 15118 Plug and Charge): OCPP, TLS and ISO 15118 Plug and Charge processing executed on a cloud server, with vendor-independent station hardware.